How Much Longer Can You Keep Patching Things Together?
TL;DR: Patching operations after disruptions work until the patches themselves start multiplying faster than the problems they were meant to solve, and that shift usually happens quietly, without a single dramatic failure to point to. The patches aren’t the problem. They’re the evidence that the underlying structure needs to change.
Key Takeaways
- Patching operations after disruptions is a short-term fix that becomes a long-term liability once it turns into the default response to every problem.
- The absence of a complaint gets mistaken for the absence of a problem, which lets patched systems limp along far longer than they should.
- Repeated patching quietly doesn’t show up as revenue, it shows up as slower recovery times and a team that’s perpetually bracing for the next disruption.
- Documenting before automating and clarifying before scaling are the two steps most businesses skip when they’re in patch mode.
- A pattern of patches in the same area of the business is a diagnostic signal, not a coincidence.
- Worth running your own version of this math before assuming the next patch will hold.
What Does It Mean to Patch Operations After Disruptions?
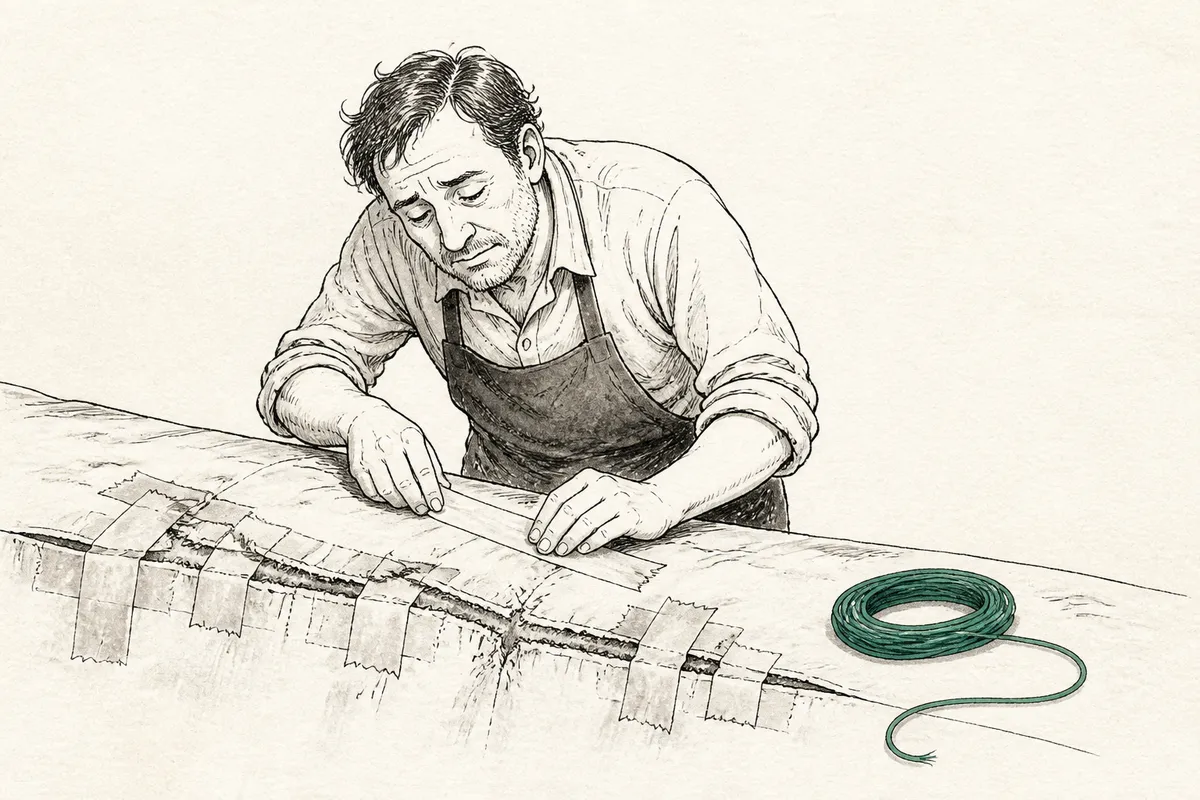
Patching operations after disruptions means applying a quick, targeted fix to restore normal function after something breaks, without addressing why it broke or whether it’ll break the same way again. It’s the phone tree rerouted after a missed call spike, the spreadsheet workaround after a system glitch, the extra approval step added after one order went out wrong. Each patch solves the immediate problem, which is exactly why it feels like progress. Here’s the honest version though, a patch is a promise that the same fix will work next time, and that promise gets harder to keep the more disruptions pile up.
That’s the entire insight, really. Patching isn’t wrong, it’s just temporary by design, built to hold something together long enough to catch your breath, not meant to be the permanent architecture underneath a growing operation. The trouble starts when temporary becomes the only mode a business knows, when every disruption gets met with another quick fix instead of a question about why disruptions keep landing in the same place.
Why Does Patching Stop Working Eventually?
Patching stops working once the number of patches outpaces anyone’s ability to remember what each one was for, why it was added, and what happens if it’s removed, which turns the operation into a structure held up by exceptions instead of design. At that point, the system isn’t fragile because of one weak spot, it’s fragile because nobody can say with confidence how the whole thing fits together anymore, and confidence is exactly what disappears first.
A system held together by patches eventually costs more to understand than it would have cost to rebuild.
That’s uncomfortable to sit with. Yes. But it’s the honest read on why a business can survive ten disruptions in a row and then get knocked flat by the eleventh, which looked no different from the others on paper. The eleventh disruption didn’t break the business, it broke the accumulated weight of everything that was already barely holding.
The Trap Hiding Inside Every Successful Patch
Here’s the trap, every time a patch works, it teaches the business that patching is a viable long-term strategy, which means the better your team gets at quick fixes, the longer the underlying problem gets to hide. A fast, competent patch feels like a win in the moment, staying level when the pressure is real, calmly rerouting around whatever just broke, and that competence is genuinely worth something. But competence at patching isn’t the same thing as a stable structure, and mistaking one for the other is how businesses end up surprised by a failure they’d technically been warned about a dozen times already.
Nobody sees the patch count. They just notice whether the operation feels steady or not, whether disruptions land and get absorbed quietly or whether every hiccup turns into a visible scramble. That feeling of steadiness, or the lack of it, is the real signal, far more reliable than whether last quarter’s numbers looked fine.
How to Tell the Difference Between a Fix and a Symptom
A fix resolves the actual cause of a disruption so it doesn’t recur in a meaningful way, while a symptom-level patch only restores function until the same underlying issue produces a new disruption somewhere else. The clearest tell is repetition, if the same category of problem keeps needing a patch even though each individual patch technically worked, that’s not bad luck, that’s a structural gap wearing a series of different disguises.
A few questions worth asking honestly about any recurring patch:
- Has this exact type of disruption happened more than twice in the past year.
- Did the last fix address why it happened, or only that it happened.
- Is the person who applied the fix the only one who understands it?
- Would a new hire be able to follow what’s actually holding this together?
If the honest answer to more than one of those is uncomfortable, that’s not a coincidence either, that’s the structure talking.
| Patch-mode operation | Structured operation |
|---|---|
| Fixes are applied by whoever’s available, in the moment | Fixes follow a documented process anyone can reference |
| Knowledge of past fixes lives in someone’s memory | Knowledge is written down and searchable |
| Same disruptions recur under slightly different names | Root causes get addressed, recurrence drops |
| Recovery time depends on who’s working that day | Recovery time is predictable regardless of who’s on shift |
| Stability feels temporary, one bad week from unraveling | Stability holds even when volume or pressure increases |
Why Documentation Comes Before Automation
Documentation has to come before automation because automating an undocumented, inconsistent process just makes the inconsistency happen faster and with less human judgment available to catch it. Documenting before automating and clarifying before scaling aren’t optional steps to skip when things are busy, they’re the difference between building something that holds up and building something that fails in a new, more expensive way.
Automating a broken process doesn’t fix it, it just breaks it faster and at greater volume.
That’s the real question underneath all of this, not “how do we patch this faster” but “why does this keep needing a patch at all.” Not a hypothetical or a sales pitch dressed up as math, just a plain look at whether the current structure is actually built for what the business has become, or whether it’s still running on assumptions from a much smaller, simpler version of itself.
Fun Fact
The concept of “technical debt,” coined by software developer Ward Cunningham in 1992, describes exactly this pattern, quick fixes that work in the short term but accumulate an invisible cost that has to be paid down eventually, usually with interest. The metaphor was built for software, but it maps almost perfectly onto operations, where every unaddressed patch is a small loan taken out against future stability.
Field Note
Systems thinking, a framework popularized in business contexts through the work of organizational theorists studying recurring failure patterns, treats repeated breakdowns as information about structure rather than isolated incidents to be solved one at a time. The core principle is straightforward, when the same type of problem shows up in different forms across time, the problem usually isn’t the individual events, it’s the design of the system producing them. Applied to operations, this means a business that keeps needing the same kind of patch isn’t unlucky, it’s getting consistent feedback about a gap in how work is structured. The framework’s practical value is that it redirects attention from blaming the latest disruption to examining the conditions that keep generating disruptions shaped like it.
FAQs
How do I know if I have a systems problem instead of a bad luck streak?
A systems problem shows up as the same category of disruption recurring in different disguises, even after each individual instance gets resolved. If you can trace three or more unrelated-seeming incidents back to the same gap, a missing handoff, an undocumented step, a single person holding critical knowledge, that’s a structural pattern, not a coincidence. Bad luck doesn’t repeat in the same shape.
What is the difference between patching and fixing an operational problem?
Patching restores function after a disruption without changing why the disruption happened, while fixing addresses the root cause so the same type of disruption becomes far less likely to recur. A patch is fast and situational. A fix takes longer, usually requires documentation or a process change, and pays off by reducing how often the team has to respond to that category of problem again.
Why does patching feel necessary even when I know it’s not a real solution?
Patching feels necessary because it produces an immediate, visible result, the disruption stops, operations resume, and the pressure of the moment lifts right away. Structural fixes don’t offer that same fast payoff, they take longer to design and implement, which makes patching the understandably tempting choice when a team is already stretched thin and needs something to work on right now.
How much does repeated patching actually cost a business?
Repeated patching costs a business in slower recovery times, concentrated knowledge risk, and a general fragility that quietly doesn’t show up as revenue on any single line item. It compounds silently, absorbed into overtime, into the owner or one key employee becoming the only person who understands how things actually hold together, and into a growing gap between how stable the business looks and how stable it actually is.
When should a business stop patching and start rebuilding a process?
A business should stop patching and start rebuilding once the same type of disruption has required a fix more than twice in a similar timeframe, or once the patch itself has become too complex for anyone besides its original author to explain. At that point, the cost of understanding the patchwork has exceeded the cost of documenting the process properly and building something that doesn’t depend on memory.
Does documenting a process really prevent future disruptions?
Documentation doesn’t prevent every disruption, but it removes the dependency on one person’s memory, which is usually the actual point of failure behind repeated patching. A documented process gives anyone on the team a consistent reference for how something is supposed to work, which shortens recovery time and makes root-cause fixes possible instead of relying on whoever happens to remember the last workaround.
Is patching always a bad approach to operational problems?
Patching isn’t always a bad approach, it’s an appropriate short-term response to an unexpected disruption when there’s no time for a full structural fix at the moment. The problem isn’t the individual patch, it’s treating patching as the permanent strategy for a recurring issue instead of using it as a temporary bridge toward a documented, repeatable fix.
Next Steps
I’ve spent enough time cleaning up messes like that to know the pattern is recognizable early, if you’re willing to look at it plainly instead of applying one more quick fix and hoping this is the last one. Worth running your own version of this math before the next disruption arrives, because it will arrive, and the only real variable is whether the structure underneath is ready for it. Talk it through with a discovery call at https://connect.greatlakesbusinesssupport.com/widget/booking/SR4YHWiGhQp2GVlUzQW4.