How Do You Reset Operations Without Stopping Everything?
A business that feels chaotic rarely needs a shutdown, it needs someone willing to isolate one broken process and fix that single piece while every other piece keeps moving, which is a different skill than the dramatic all-hands reset most owners picture when they hear the word. That’s the entire insight, honestly. The instinct to stop everything, rebuild from scratch, and relaunch clean feels satisfying because it feels decisive, but it also stops the revenue, stalls client work, and creates a gap that didn’t need to exist. Resetting operations without stopping is slower to look at and faster to actually finish.
What does it mean to reset operations without stopping?
Resetting operations without stopping means identifying and repairing one broken workflow at a time while every other part of the business continues serving clients and generating revenue, rather than pausing all operations to rebuild everything simultaneously. It treats the business like a set of separate processes, intake, fulfillment, billing, follow up, each of which can be documented, tested, and improved on its own schedule. Nothing about this requires downtime. It requires sequencing. A workflow is simply a repeatable series of steps that produces a consistent outcome, and once a workflow is written down, it can be examined for weak points without touching the workflows around it.
Here’s the honest version: most operational messes aren’t one big problem, they’re several small unattended ones that got lumped together because nobody separated them. Once they’re separated, each one gets small enough to fix without anyone noticing the fix happened.
Why do businesses think they need a full stop first?
Businesses default to the idea of a full stop because the mess feels total, even when the actual damage is contained to two or three specific processes that got tangled together over time. A full stop feels like control. It signals seriousness, it gives the appearance of a fresh start, and it matches the emotional weight of feeling behind. But operationally, a full stop is expensive in ways that don’t show up on an invoice. It quietly doesn’t show up as revenue, because clients still expect delivery, invoices still need to go out, and phones still ring whether or not the business declared a reset.
Nobody sees the internal mess. They just notice whether it feels steady or not.
That’s the honest version. The client on the other end of a service call has no idea whether the intake process is a mess behind the scenes, they only know whether their call got returned, their invoice was accurate, and their job got done on time.
How do you pick the first process to fix?
The first process to fix is whichever one currently causes the most repeated, low-visibility friction, typically something like intake, scheduling, or handoffs between people, because these are the workflows that touch every other part of the business downstream. Start with documenting before automating. Write down what actually happens right now, step by step, including the workarounds nobody officially approved but everyone quietly uses. That document becomes the map. Without it, any fix is a guess dressed up as a decision.
A few signals point to which process needs attention first:
- It requires the owner’s direct involvement to function at all.
- It has broken more than once in the last few months without a permanent fix.
- It creates confusion between two or more people who each think the other one owns it.
- Clients have quietly adjusted their own expectations around its inconsistency.
- Fixing it would free up a measurable amount of time each week.
That last one matters more than it sounds. The absence of a complaint gets mistaken for the absence of a problem, when in fact the client just stopped mentioning it and started routing around it instead.
What does fixing one process at a time actually look like?
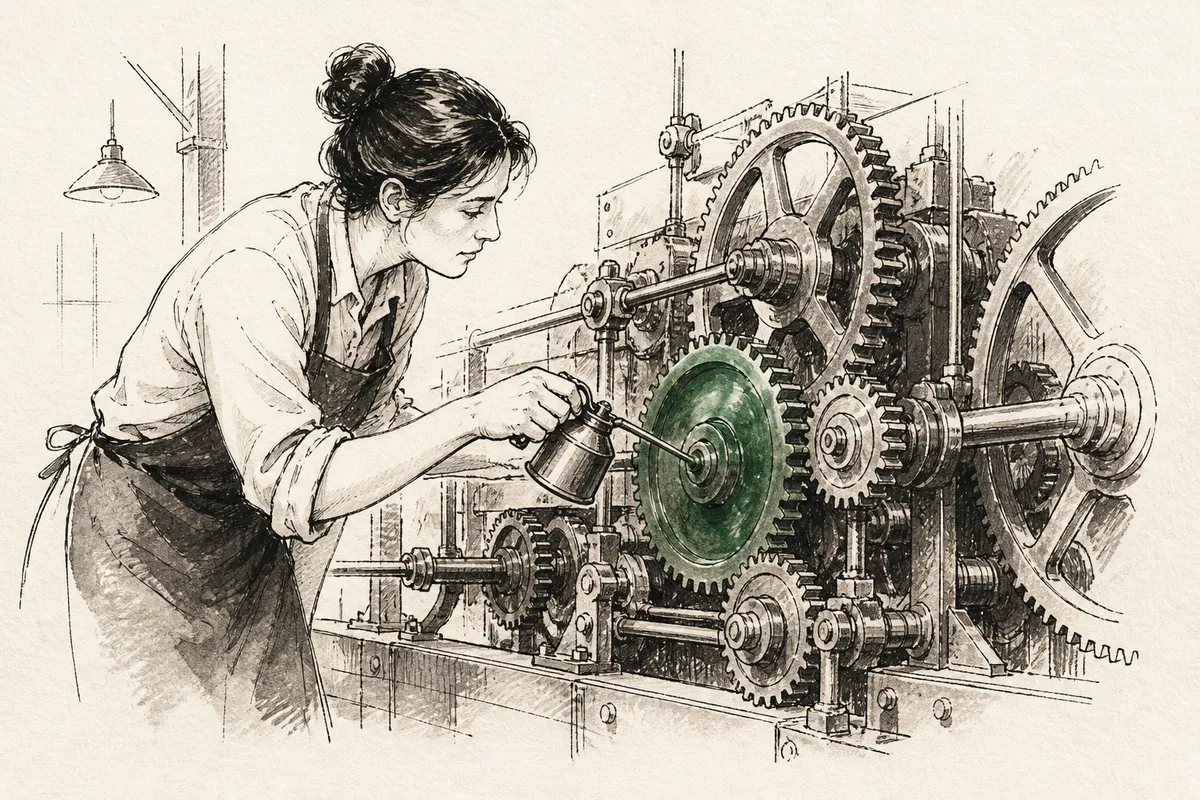
Fixing one process at a time means documenting the current steps, identifying the single weakest link in that specific workflow, testing a change against real work, and confirming it holds before touching anything else, all while the rest of the business operates exactly as it did before. It is not a redesign of the whole operation. It is a narrow, contained repair. The rest of the business, including the other processes that still have their own quirks, keeps running untouched during this window.
That’s the trap worth naming directly. Owners often want to fix everything they’ve spotted at once, because once the flaws are visible, they’re hard to ignore individually. But clarifying before scaling means resisting that urge. A single process, clarified and stable, is worth more than five processes half touched.
| Approach | What happens to client work | Typical outcome |
|---|---|---|
| Full operational stop | Paused or delayed during rebuild | High disruption, faster to feel “done” |
| One process at a time | Continues without interruption | Lower disruption, slower to feel finished, more durable |
| No structured reset | Continues, but issues compound | Problems resurface repeatedly, no lasting fix |
Why does this approach protect revenue?
This approach protects revenue because client-facing work never pauses, invoices keep going out, deliveries keep happening, and the business keeps generating income while the internal repair happens quietly in the background rather than in front of the client. Revenue depends on continuity, not on how clean the internals look on any given day. A business can have a genuinely awkward internal process and still bill consistently, as long as the client-facing side holds steady while the fix happens underneath it.
That’s the entire insight. Fix the process, not the calendar.
Staying level when the pressure is real is what separates a contained repair from a chaotic one. The pressure to fix everything now is real, and ignoring that pressure long enough to sequence the work properly is the actual discipline here.
Fun Fact
The term “business process reengineering” was popularized in a 1990 Harvard Business Review article, and even then, the original argument was about redesigning workflows individually for dramatic improvement, not shutting an entire organization down to rebuild it from zero. The idea of a total operational stop was never actually part of the original concept, it got attached to it later by people looking for a dramatic before-and-after story.
Field Note
Systems thinking, a framework used across engineering and operations management, treats an organization as a set of interconnected but separable parts rather than a single monolithic machine. The core principle is that a system can be improved locally, one component at a time, without requiring the whole system to be taken offline, because the interfaces between components are what need to stay stable, not the components themselves. Applied to a small business, this means the phone system, the invoicing process, and the client onboarding sequence are three separate components with a shared interface. Fixing one doesn’t require disturbing the others, as long as the handoff points between them are respected during the repair. That’s the mechanical reason a full stop is rarely necessary. The parts were never as fused together as they looked from the outside.
FAQs
How do I know if I have a systems problem?
A systems problem usually shows up as repeated friction around the same task, done by different people, at different times, with no permanent fix ever sticking. If the same issue keeps resurfacing despite individual effort to patch it, the problem is the process itself, not the person handling it that day. Look for tasks where multiple people have independently created their own workaround, since that’s a strong sign the underlying workflow was never actually documented.
What is the first step in resetting operations without stopping?
The first step is documenting the current process exactly as it happens today, including the informal workarounds, before deciding what to change. Documentation creates a shared, accurate picture of reality, which is different from what the process was supposed to look like on paper. Without that step, any fix is based on assumption rather than what’s actually occurring.
How long does it take to fix one process without stopping everything else?
The timeline depends entirely on the complexity of the process and how many people touch it, but a single contained workflow can often be documented, tested, and stabilized within a few weeks of focused attention. Complex processes with several handoff points take longer. The point isn’t speed, it’s containment, keeping the repair isolated so nothing else gets disrupted while it’s underway.
Can I reset operations while still taking on new clients?
Yes, and that is the entire premise of a staged reset rather than a full stop. Because the fix is isolated to one process at a time, client-facing work, including new client intake, continues on the existing workflow until its specific turn in the sequence comes up. This is only risky if the process being repaired is the same one handling new client intake at that exact moment, in which case extra care during testing is warranted.
What is the difference between a full operational stop and a staged reset?
A full operational stop pauses most or all business activity to rebuild broadly, while a staged reset repairs one process at a time while every other process, and client delivery, continues uninterrupted. The staged approach takes longer to feel completely finished but avoids the revenue and trust costs of a visible pause. It also allows each fix to be tested against real conditions rather than theoretical ones.
Why do some fixes fail even after a full stop?
Fixes made during a full stop often fail because they were designed in isolation from real operating conditions, without the pressure and variability of live client work to test them against. A process redesigned on a whiteboard behaves differently once real clients, real timing, and real exceptions get introduced. That’s not a hypothetical or a sales pitch dressed up as math, it’s a documented pattern in how process redesign efforts commonly underperform once implemented against real conditions.
How do I prioritize which process to fix first when everything feels broken?
Start with whichever process touches the most other workflows downstream, since fixing it reduces friction across multiple areas at once rather than just one. Intake and handoff points between people or departments are common starting places because they affect everything that happens afterward. It’s worth running your own version of this math against your specific operation before assuming the most visible problem is actually the most connected one.
Next Steps
A reset doesn’t require a dramatic pause, it requires a clear, sequenced list of which process to fix first and why. Get a prioritized list with a Free Website & Workflow Review at https://www.greatlakesbusinesssupport.com/free-website-workflow-review.